33 Building a phylogenetic tree
33.1 Background
This activity builds intuition for phylogenetic trees by using discrete morphological characters. It follows the classroom activity by Wojciech Grajkowski, Building a phylogenetic tree (Bioscience Explained 6(2)), which you can download here as a PDF. The PDF includes the organism cards and a worksheet.
Reading: Neal, chapter Darwin’s Evolutionary Theories (common descent and Darwin’s “tree of life”).
Learning outcomes:
- Build a simple character table for a set of organisms.
- Compute pairwise differences and translate them into a tree.
- Relate morphology-based trees to the idea of evolutionary relatedness, and recognise when similarity may not reflect relatedness.
33.2 Key idea
With six organisms and seven characters, you can compute a pairwise difference table, then group the most similar organisms first. The internal nodes of the tree represent inferred common ancestors: the pairs joined first represent the most recent common ancestors, and the deeper splits represent older ones.
A caveat: similarity is not the same as relatedness. Grouping organisms by overall similarity (the method used here, which is called UPGMA when done by computer) recovers the true tree only if characters change at a roughly constant rate in all lineages and the same character state never evolves more than once. In reality, unrelated organisms can evolve the same feature independently (convergence, e.g. wings in birds and bats, or loss of thorns in several plant lineages), and features can be lost again (reversal). Some shared features are also simply inherited from a distant ancestor of the whole group (ancestral states) and say nothing about who is most closely related. Modern phylogenetics therefore groups organisms by shared derived characters (new features that arose in their common ancestor), uses an outgroup to decide which states are ancestral, and increasingly uses DNA sequences. Keep this in mind when you interpret your tree.
33.3 Worked example
The PDF’s example has six beetle-like organisms (A to F), described by seven characters:
beetles <- data.frame(
  row.names    = c("A", "B", "C", "D", "E", "F"),
  body_shape   = c("Oval", "Oval", "Round", "Oval", "Round", "Round"),
  colour       = c("Yellow", "Yellow", "Orange", "Pink", "Pink", "Orange"),
  head_colour  = c("White", "Black", "Black", "White", "Black", "Black"),
  antennae     = c("No", "No", "No", "Yes", "Yes", "No"),
  jaws_visible = c("Yes", "Yes", "Yes", "No", "No", "Yes"),
  spots        = c("Yes", "Yes", "Yes", "No", "No", "Yes"),
  spot_colour  = c("Black", "Black", "Black", "None", "None", "White")
)
beetles
## body_shape colour head_colour antennae jaws_visible spots spot_colour
## A Oval Yellow White No Yes Yes Black
## B Oval Yellow Black No Yes Yes Black
## C Round Orange Black No Yes Yes Black
## D Oval Pink White Yes No No None
## E Round Pink Black Yes No No None
## F Round Orange Black No Yes Yes WhiteNext, count the number of characters that differ between each pair of organisms. This is the “data matrix” in the PDF:
n <- nrow(beetles)
differences <- matrix(0, nrow = n, ncol = n,
                      dimnames = list(rownames(beetles), rownames(beetles)))
for (i in 1:n) {
  for (j in 1:n) {
    differences[i, j] <- sum(beetles[i, ] != beetles[j, ])
  }
}
differences
## A B C D E F
## A 0 1 3 5 7 4
## B 1 0 2 6 6 3
## C 3 2 0 7 5 1
## D 5 6 7 0 2 7
## E 7 6 5 2 0 5
## F 4 3 1 7 5 0Finally, join the most similar organisms first (Figure 33.1). The function hclust with method = "average" does this automatically: at each step it joins the two closest groups, measuring the distance between groups as the average number of differences between their members.
tree <- hclust(as.dist(differences), method = "average")
plot(tree, main = "", xlab = "", sub = "",
     ylab = "Average number of differences")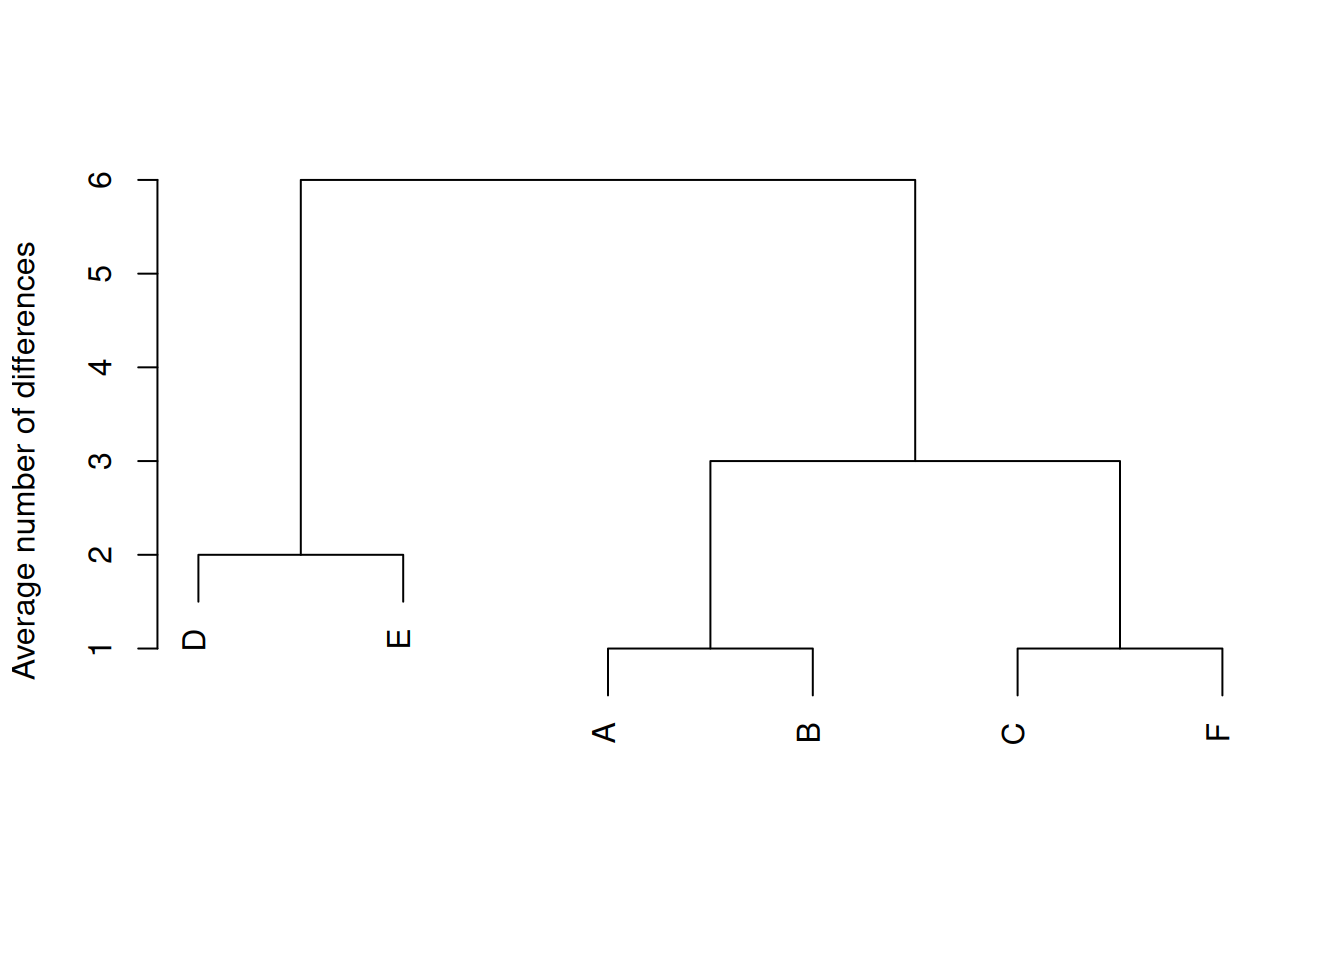
Figure 33.1: Tree for the six beetle-like organisms in the PDF, built by joining the most similar organisms first (UPGMA). The height of each join is the average number of character differences between the two groups.
A and B differ in only one character, as do C and F, so these pairs are joined first (at a height of 1): they share the most recent common ancestors. D and E (2 differences) are joined next, then the A+B and C+F groups (an average of 3 differences), and finally the two main groups. This is the same tree as the one drawn by hand in the PDF.
Now look back at the character table. On this tree, no single change can explain body shape or head colour. E is round like C and F, but groups with D, and A has a white head like D, but groups with B. At least one of these characters must have changed more than once (convergence or reversal). Which one, and in which direction, cannot be decided without knowing the ancestral states, for example from an outgroup.
33.4 Your task
Use the PDF as a guide for the classroom activity.
- Pick six organisms (use the cards in the PDF: plants, birds or butterflies, or invent six organisms with clear traits).
- Identify seven discrete characters that differ among the organisms (presence/absence, colour class, tail length category, etc.).
- Fill in a character table and then compute a pairwise difference table.
- Draw a phylogenetic tree by grouping the most similar organisms first, then adding deeper splits.
- Identify any characters that look convergent on your tree (the PDF’s “Additional questions”).
- Optional: compare your hand-drawn tree with an R result, by replacing the
beetlestable in the worked example with your own character table.
33.5 Takeaways
- Morphological characters can be converted into a simple distance matrix.
- The most similar pairs in the distance matrix are joined first, and represent the most recent common ancestors in the tree.
- Overall similarity is not the same as relatedness: convergence and reversals can mislead, which is why phylogenetics relies on shared derived characters and on many characters, including DNA.